Posts by Collection

portfolio

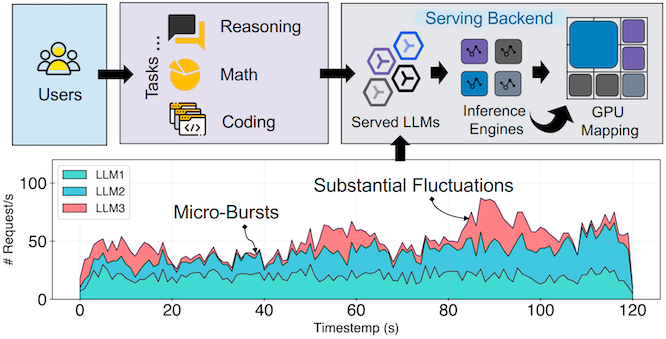
High-Performance Inference & Serving for LLMs

Accelerating the inference speed and improving the serving quality of popular large language models through system-level optimizations. We focus on efficient deployment across heterogeneous GPUs and support for advanced model features like multimodal and long-context.
Pre/Post-Training System for LLM

Optimizing the training efficiency through high-performance kernels and parallel techniques. We focus on extracting peak performance from GPU/CPU hardwares to accelerate training speed.

publications

talks

teaching

Computer Architecture

Undergraduate Course (Assistant), School of Computer and Communication Engineering, 2026

Data Structure

Undergraduate Course, School of Computer and Communication Engineering, 2027