High-Performance Inference & Serving for LLMs
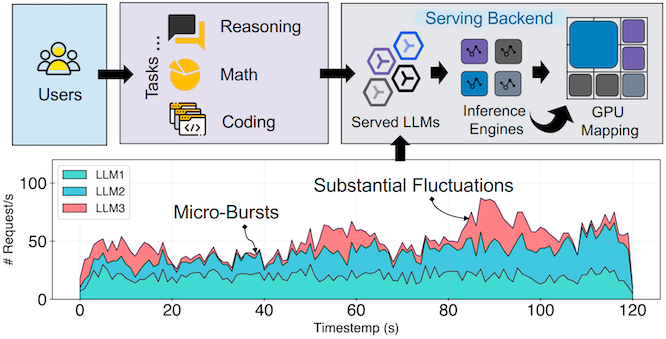
Accelerating the inference speed and improving the serving quality of popular large language models through system-level optimizations. We focus on efficient deployment across heterogeneous GPUs and support for advanced model features like multimodal and long-context.